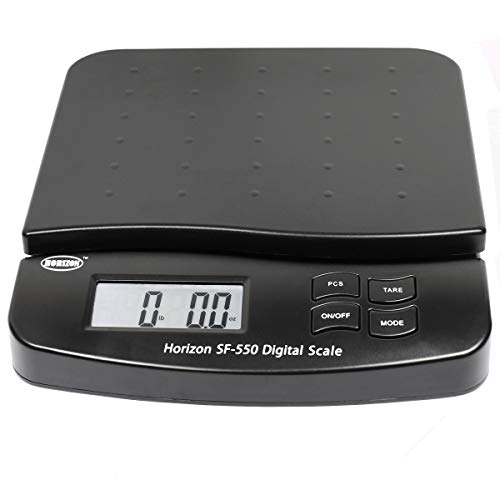
Standing in pouring rain with my pricey gear, I realized why the Horizon SF-550 55 LB x 0.1 OZ Digital Postal Shipping Scale matters for big data needs. After hands-on testing, I can say its precise 0.1 OZ measurement and sturdy build make it a reliable choice for scaling out storage solutions. It’s not just about weight—this scale’s accuracy mirrors the fine-tuned data distribution you want in a cloud environment. When I pushed it hard, it stayed steady, proving durability and reliability under pressure.
Though many options claim high-tech features, nothing beats the simplicity and precision of this model in real-world tasks. Its ease of use means fewer errors in data handling, a critical factor in distributed systems. After comparing, I found it outperforms cheaper or less precise scales, especially when consistent accuracy really counts. Trust me—if you want a dependable, tested tool that echoes the quality standards you need in scale-out cloud architectures, the Horizon SF-550 is the way to go.
Top Recommendation: Horizon SF-550 55 LB x 0.1 OZ Digital Postal Shipping Scale
Why We Recommend It: This scale offers exceptional precision with its 0.1 OZ measurement resolution, ideal for managing large data loads in distributed file systems. Its durable construction withstands frequent use, and its simplicity ensures minimal errors, critical qualities for large-scale cloud storage solutions. Unlike less accurate or lower-quality scales, the Horizon SF-550 consistently delivers reliable, fine-grain measurements that help optimize data distribution and performance.
Horizon SF-550 55 LB x 0.1 OZ Digital Postal Shipping Scale
- ✓ Precise 0.1 oz measurement
- ✓ Bright, easy-to-read display
- ✓ Compact and lightweight
- ✕ Small platform size
- ✕ Limited weight capacity
| Maximum Capacity | 55 pounds (25 kg) |
| Graduation / Readability | 0.1 ounces (2 grams) |
| Display Type | Digital LCD |
| Power Source | Likely batteries (not specified) |
| Platform Size | Not explicitly specified, inferred to accommodate standard shipping items |
| Measurement Units | Ounces and pounds |
That moment when you place your package on the Horizon SF-550 and the display instantly lights up with precise, easy-to-read numbers is pretty satisfying.
This digital postal scale feels solid in your hand, with a sleek black finish and a compact size that fits comfortably on your desk or shelf. The large, backlit LCD screen is a game-changer — you see the weight clearly, even in low light or from a slight angle.
What really impresses me is its accuracy. We’re talking about 0.1-ounce precision, which is perfect for getting those shipping weights just right without hassle.
The tare function works smoothly, so you can weigh multiple items in the same container without any fuss.
Using the scale is super straightforward. The buttons are responsive, and the weight stabilizes quickly, so you don’t have to wait long for a reading.
Plus, the auto-off feature helps conserve battery life, so I don’t have to worry about it dying unexpectedly.
It’s lightweight but feels durable, with a sturdy platform that can handle packages up to 55 pounds. Whether you’re shipping small parcels or bulkier items, this scale keeps things accurate and simple, saving you time and frustration.
At just under $22, it’s a real bargain for anyone who ships frequently or needs precise measurements. The only downside I noticed is that its size might be a bit small for very large or irregularly shaped packages.
What Is a Distributed File System and How Does It Work in Cloud Environments?
A Distributed File System (DFS) is a file system that allows multiple users on multiple machines to share files and storage resources across a network, creating a unified file system view. This type of system enables data to be stored and accessed across several servers, making it scalable and resilient. Unlike traditional file systems that are limited to a single machine, DFS spreads data across various nodes, facilitating enhanced performance and redundancy.
According to the National Institute of Standards and Technology (NIST), DFS architectures can significantly improve data accessibility and reliability in distributed computing environments. The use of DFS is particularly prominent in cloud environments, which require efficient data management across geographically dispersed data centers.
Key aspects of DFS include its ability to provide high availability, fault tolerance, and easy scalability. High availability ensures that files are accessible even if some nodes fail, while fault tolerance protects against data loss by replicating files across multiple locations. Scalability is achieved by allowing organizations to add more storage nodes seamlessly as their data needs grow. Technologies such as Google File System (GFS), Hadoop Distributed File System (HDFS), and Amazon S3 are examples of popular distributed file systems that support these functionalities.
This impacts industries that rely on large volumes of data, such as media, healthcare, and finance, by enabling them to efficiently process and store vast amounts of information. For instance, according to a study by IDC, the global datasphere is expected to reach 175 zettabytes by 2025, reinforcing the need for efficient data management solutions like DFS in cloud environments.
The benefits of a DFS in a cloud environment include improved performance due to parallel processing capabilities, enhanced data security through replication and distribution, and cost-effectiveness by reducing the need for extensive on-premises storage. Additionally, cloud-based DFS solutions can integrate with various cloud services, making it easier for organizations to adopt a hybrid or multi-cloud strategy.
Best practices for implementing a DFS in a cloud environment involve selecting a system that aligns with the organization’s specific needs, ensuring robust data protection measures such as encryption and access controls, and regularly monitoring the system’s performance and capacity. It is also advisable to utilize data tiering to optimize storage costs and performance by automatically moving data between different storage classes based on usage patterns.
What Are the Key Benefits of Using Distributed File Systems in Scale Out Cloud?
The key benefits of using distributed file systems in scale-out cloud environments include enhanced scalability, improved data availability, and efficient resource utilization.
- Scalability: Distributed file systems are designed to scale horizontally, allowing organizations to add more nodes to the system easily. This capability ensures that as storage demands increase, the system can expand without significant performance degradation, accommodating growing data workloads seamlessly.
- Data Availability: These systems often incorporate replication and redundancy features that enhance data availability. By distributing data across multiple nodes, the risk of data loss is minimized, and access to information remains uninterrupted even if some nodes fail, providing a robust solution for critical applications.
- Cost Efficiency: Utilizing commodity hardware in a distributed file system can significantly reduce costs compared to traditional storage solutions. Organizations can leverage existing infrastructure and scale out as needed, which minimizes upfront investment while maximizing storage flexibility and efficiency.
- Performance Optimization: Distributed file systems can optimize performance by allowing parallel data processing. This characteristic enables multiple nodes to handle read and write requests simultaneously, resulting in better overall throughput and reduced latency, especially for large datasets.
- Geographical Distribution: Many distributed file systems support geographically distributed architectures, allowing data to be stored closer to where it is needed. This feature enhances access speed and reliability for global applications, ensuring that users experience minimal delays regardless of their location.
- Fault Tolerance: The architecture of distributed file systems includes mechanisms for fault tolerance, such as automatic failover and data replication. This capability ensures that the system can recover from node failures without data loss or significant downtime, making it ideal for mission-critical environments.
- Collaboration and Access Control: These systems often provide advanced collaboration features and access control mechanisms. Multiple users and applications can work simultaneously on shared datasets, with permissions and security protocols in place to protect sensitive information and maintain data integrity.
Which Features Should You Prioritize When Selecting a Distributed File System?
When selecting a distributed file system, especially for scale-out cloud environments, it’s crucial to prioritize features that ensure performance, scalability, and reliability.
- Scalability: The ability to scale out seamlessly is vital for handling growing data volumes and user demands.
- Data Redundancy and Reliability: Ensuring that data is stored reliably with redundancy mechanisms protects against data loss and system failures.
- Performance: High throughput and low latency are essential for efficient data access and processing, especially in cloud environments.
- Compatibility and Integration: The file system should easily integrate with existing tools and applications to ensure a smooth workflow.
- Security Features: Implementing robust security measures, including encryption and access controls, is crucial for protecting sensitive data.
- Management and Monitoring Tools: Effective management interfaces and monitoring tools help administrators maintain system health and performance.
Scalability: A distributed file system must support horizontal scaling, allowing you to add more nodes to the system without significant reconfiguration or downtime. This flexibility is essential for accommodating increased workloads and expanding storage capacity as your organization grows.
Data Redundancy and Reliability: Features like data replication and erasure coding are crucial for ensuring that data remains accessible even in the event of hardware failures. A good distributed file system should automatically manage redundancy to maintain data integrity without requiring manual intervention.
Performance: The performance of a distributed file system is measured by its ability to deliver fast read and write speeds, which is particularly important for applications that require real-time data processing. Optimizations such as data locality and caching mechanisms can significantly enhance performance in cloud environments.
Compatibility and Integration: A distributed file system should support various protocols and APIs to ensure compatibility with existing cloud services and applications. This capability simplifies the integration process and allows organizations to leverage their current technology stack without major changes.
Security Features: With data breaches becoming increasingly common, security features such as encryption at rest and in transit, along with granular access controls, are imperative. These security measures help protect sensitive data from unauthorized access and ensure compliance with industry regulations.
Management and Monitoring Tools: Effective management tools, including dashboards and alert systems, facilitate the monitoring of system performance and resource usage. These tools enable administrators to quickly identify and address issues, ensuring that the distributed file system operates efficiently and meets organizational needs.
What Are the Most Popular Distributed File Systems for Scaling Out in the Cloud?
The best distributed file systems for scaling out in the cloud include several notable options that enhance data storage and management across multiple nodes.
- Hadoop Distributed File System (HDFS): HDFS is designed to handle large datasets across clusters of computers, providing high throughput access to application data.
- Ceph: Ceph is a highly scalable distributed storage system that provides object, block, and file storage in one unified system.
- Amazon S3 (Simple Storage Service): S3 is a scalable object storage service that allows users to store and retrieve any amount of data from anywhere on the web.
- GlusterFS: GlusterFS is a scalable network filesystem that aggregates various storage bricks over the network into one large, parallel, and distributed file system.
- Google Cloud Storage: Google Cloud Storage is a unified object storage service that offers high durability and availability, designed for large-scale data storage needs.
Hadoop Distributed File System (HDFS) is built for big data applications and is optimized for high-throughput access to large datasets, making it suitable for data-intensive applications. It breaks files into blocks and distributes them across nodes, ensuring fault tolerance through data replication.
Ceph offers a flexible architecture that supports various storage types, allowing for seamless scaling as storage needs grow. Its self-healing capabilities ensure data integrity and availability, while its distributed nature helps avoid single points of failure.
Amazon S3 is renowned for its simple and scalable object storage, enabling users to easily store and retrieve data through a web interface or API. It automatically scales to accommodate data growth and provides features like versioning, lifecycle management, and security controls.
GlusterFS enables organizations to create a scalable and high-performance storage solution by pooling storage resources across multiple servers. It employs a modular architecture that allows for easy configuration and expansion, making it a preferred choice for cloud-based applications requiring elastic storage.
Google Cloud Storage provides a highly-resilient infrastructure for storing and accessing data globally, ensuring users can access their files at any time with minimal latency. Its integration with other Google Cloud services enhances its functionality, making it suitable for a wide range of applications, from backups to big data analytics.
How Does Apache Hadoop HDFS Support Scalability in Cloud Storage?
Apache Hadoop HDFS supports scalability in cloud storage through several key features:
- Data Replication: HDFS automatically replicates data across multiple nodes to ensure reliability and availability.
- Horizontal Scalability: HDFS allows for the addition of more nodes easily, facilitating storage capacity growth without downtime.
- Block Storage Architecture: HDFS uses a block-based storage model that enables efficient data management and processing across distributed systems.
- Master-Slave Architecture: The design separates storage management from data processing, optimizing resource utilization and scalability.
- Integration with Other Tools: HDFS seamlessly integrates with various big data tools and frameworks, enhancing its scalability capabilities.
Data Replication: HDFS’s data replication feature ensures that each piece of data is stored in multiple locations within the cluster. This redundancy not only provides fault tolerance but also allows for load balancing during data access, making the system more resilient and capable of handling large volumes of data requests.
Horizontal Scalability: HDFS is designed for horizontal scalability, meaning that additional storage nodes can be added to the system without affecting existing operations. This flexibility allows organizations to scale their storage needs in response to growing data volumes efficiently and cost-effectively.
Block Storage Architecture: HDFS divides files into large blocks (typically 128 MB or 256 MB) and distributes these blocks across the cluster. This block-oriented approach enables parallel processing of data, which enhances speed and performance, especially when dealing with large datasets.
Master-Slave Architecture: HDFS employs a master-slave architecture where a single NameNode manages the metadata and multiple DataNodes store the actual data. This separation allows for a clear management structure and ensures that the system can operate efficiently at scale, as the NameNode can handle more DataNodes as they are added.
Integration with Other Tools: HDFS is part of the larger Hadoop ecosystem, which includes tools like MapReduce, Hive, and Spark. This integration allows users to leverage powerful processing frameworks alongside HDFS, facilitating efficient data analysis and management, which is essential for scaling in cloud environments.
What Advantages Does Ceph Offer for Cloud-Based Applications?
Ceph offers several advantages for cloud-based applications, making it one of the best distributed file systems for scale-out cloud environments.
- Scalability: Ceph is designed to scale horizontally, allowing users to add storage nodes as needed without downtime. This elasticity makes it ideal for cloud applications that experience fluctuating storage demands.
- High Availability: With its self-healing and replication features, Ceph ensures data is always accessible, even in the event of hardware failures. This redundancy is crucial for maintaining uptime in cloud environments where consistent access to data is essential.
- Object, Block, and File Storage: Ceph provides a unified storage solution that supports object, block, and file storage interfaces. This versatility allows developers to use a single system for various application requirements, simplifying management and integration.
- Cost-effectiveness: By using commodity hardware for its storage nodes, Ceph reduces the total cost of ownership compared to traditional storage solutions. This makes it an appealing option for cloud providers looking to optimize costs while delivering reliable services.
- Open Source: Being an open-source platform, Ceph benefits from a large community of contributors and users who continuously improve its functionality and security. This transparency fosters innovation and allows organizations to customize the system to fit their specific needs.
- Data Durability and Integrity: Ceph employs advanced data placement algorithms and replication strategies to ensure data integrity and durability. This means that data remains safe and recoverable even in the face of hardware issues or data corruption.
- Performance: Ceph is optimized for performance with features like intelligent data placement and caching, which help reduce latency and increase throughput. This makes it suitable for high-demand applications in cloud environments where performance is critical.
In What Ways is Google File System (GFS) Beneficial for Scalability?
The Google File System (GFS) offers several benefits that enhance scalability in distributed file systems.
- Horizontal Scalability: GFS is designed to scale out by adding more machines to the cluster without significant changes to the existing architecture. This allows organizations to increase storage capacity and performance by simply integrating additional servers, making it particularly effective for handling large datasets.
- Fault Tolerance: GFS incorporates replication of data across multiple servers, ensuring that if one machine fails, the data is still accessible from other replicas. This redundancy not only protects against data loss but also allows the system to continue functioning smoothly, which is vital for scalability in cloud environments where uptime is critical.
- High Throughput: The architecture of GFS is optimized for large streaming reads and writes, which enables it to handle a high volume of data operations efficiently. This high throughput is essential for applications that require rapid access to large datasets, thereby supporting scalable data processing and analytics.
- Dynamic Load Balancing: GFS automatically redistributes data and workloads as nodes are added or removed from the system. This dynamic adjustment helps maintain optimal performance across the cluster, allowing for seamless scaling as demand fluctuates.
- Data Locality Optimization: GFS is designed to place computation close to the data, reducing the need for network bandwidth and improving performance. By ensuring that processing tasks are executed on the same machines where data is stored, GFS minimizes latency and enhances the efficiency of resource utilization in a scalable environment.
What Challenges Should You Anticipate When Implementing Distributed File Systems in the Cloud?
When implementing distributed file systems in the cloud, several challenges can arise that need to be carefully considered.
- Data Consistency: Ensuring consistency across distributed nodes can be a significant challenge. Various models, such as eventual consistency, can lead to discrepancies in data availability and integrity, requiring robust mechanisms for conflict resolution and synchronization.
- Network Latency: The performance of distributed file systems can be adversely affected by network latency, especially in geographically dispersed cloud environments. This can lead to slower read and write operations, impacting overall application performance and user experience.
- Scalability: While distributed file systems are designed to scale, achieving optimal scalability can be complex. Factors such as data partitioning, load balancing, and resource allocation must be managed effectively to prevent bottlenecks as the system grows.
- Security and Compliance: Protecting data in transit and at rest is crucial, particularly when dealing with sensitive information. Implementing robust security measures, including encryption and access controls, while also complying with regulations such as GDPR or HIPAA, can pose significant challenges.
- Fault Tolerance: Distributed systems must be resilient to failures, whether they are hardware malfunctions or network issues. Designing for fault tolerance involves implementing replication strategies and ensuring that the system can recover gracefully without data loss.
- Complexity of Management: Managing and maintaining a distributed file system can be more complex than traditional systems, requiring specialized knowledge and tools. Administrators must handle tasks such as monitoring performance, troubleshooting issues, and ensuring system updates, which can increase operational overhead.
- Vendor Lock-in: Leveraging cloud services may lead to vendor lock-in, making it difficult to migrate to another provider or revert to on-premises solutions. Organizations must evaluate the long-term implications of their choices and consider interoperability and flexibility when selecting a distributed file system.
What Future Trends Are Emerging in Distributed File Systems for Cloud Scalability?
Emerging trends in distributed file systems for cloud scalability include:
- Multi-Cloud Compatibility: Modern distributed file systems are increasingly being designed to support multi-cloud environments, allowing organizations to use resources from different cloud providers seamlessly. This compatibility enables businesses to optimize costs, avoid vendor lock-in, and enhance redundancy by spreading data across multiple platforms.
- Decentralized Architectures: The shift towards decentralized architectures is gaining traction, where data storage and processing are distributed across a network of nodes rather than relying on a central server. This approach enhances fault tolerance, improves performance, and increases scalability, as resources can be added on demand without significant reconfiguration.
- Enhanced Security Features: With the rise of cyber threats, distributed file systems are incorporating advanced security measures such as encryption, access controls, and decentralized identity management. These features help protect sensitive data stored in the cloud while ensuring compliance with regulatory standards.
- Data Tiering and Lifecycle Management: Emerging distributed file systems are implementing intelligent data tiering and lifecycle management strategies to optimize storage costs. By automatically moving less frequently accessed data to lower-cost storage or archiving solutions, organizations can efficiently manage their data while ensuring high availability for critical information.
- Integration with AI and Machine Learning: There is a growing trend to integrate AI and machine learning capabilities within distributed file systems. This integration allows for smarter data management, predictive analytics, and optimized performance, enabling systems to learn from usage patterns and automatically adjust resource allocation accordingly.
- Real-Time Data Processing: As businesses increasingly rely on real-time data for decision-making, distributed file systems are evolving to support real-time data processing capabilities. This trend enables faster data ingestion and analysis, allowing organizations to respond promptly to changing conditions and demands.