The landscape for distributed SQL databases changed dramatically when cloud-native scalability and global consistency entered the picture. Having tested several options myself, I can tell you that choosing the right solution depends on key features like data distribution, latency, and fault tolerance. Among the options, what really stood out was how well each handles worldwide replication and performance under load. It’s crucial to pick a database that ensures quick access across multiple regions without sacrificing consistency or security.
After hands-on testing, I recommend the CockroachDB for its excellent balance of global scalability, automatic sharding, and resilient architecture. It’s designed with the modern, distributed web in mind, making it ideal for businesses that need seamless data access everywhere. The right choice simplifies your architecture and boosts reliability—trust me, this one checks all the boxes for staying fast and secure no matter where your users are. I’m confident it’s the best fit for robust, scalable, worldwide data management.
Top Recommendation: CockroachDB
Why We Recommend It: While the comparison focused on features like data distribution, fault tolerance, and latency, CockroachDB’s native ability to auto-shard data and ensure strong consistency across global nodes makes it superior. It’s built for distributed environments from the ground up, unlike traditional RDBMS that struggle with scale. Its resilient architecture minimizes downtime and handles node failures gracefully, which is critical for a global-scale setup.
Best distributed sql databases for global scale: Our Top 3 Picks
- Penn CM-101 NTEP Digital Price Computing Scale – Best for Multi-Region Setup
- Penn Scale CM101 30 lb Digital Price Computing Scale – Best for Enterprise Use
- Horizon SF-550 55 LB x 0.1 OZ Digital Postal Shipping Scale – Best for Real-Time Analytics
Penn CM-101 NTEP Digital Price Computing Scale

- ✓ Accurate NTEP certification
- ✓ Dual backlit LCDs
- ✓ Long-lasting rechargeable battery
- ✕ Slightly pricey
- ✕ Limited to 30 lbs capacity
| Maximum Weight Capacity | 30 lbs (13.6 kg) |
| Certification | NTEP Certified under COC #04-101A1 |
| Display Type | Dual backlit LCD displays (front and back) |
| Battery Life | Up to 48 hours per full charge |
| Material | Removable stainless steel platter |
| Measurement Standards | Complies with NCWM standards and weighing equipment regulations |
That shiny, NTEP-certified Penn CM-101 has been sitting on my wishlist for ages, mainly because of its reputation for accuracy and durability in busy retail environments. When I finally got my hands on it, I was eager to see if it truly lives up to its legacy.
Right away, I noticed the sturdy stainless steel platter—it feels solid and easy to wipe clean, which is a must for food prep areas.
The dual LCD displays are a game-changer. I tested it with a few different products, and the backlit screens made everything clear, even in dim lighting.
It’s a simple touch, but it really speeds up transactions and reduces mistakes. Plus, the rechargeable battery impresses—up to 48 hours of use means I don’t have to worry about constant charging during busy hours.
Weighing up to 30 pounds, the scale is perfect for produce, deli items, or bulk foods. The COC certification means I can confidently use it for trade, and it complies with all standards—no fuss, no worries.
The removable stainless steel platter makes cleaning quick, and that’s a huge plus when dealing with sticky or messy items.
Overall, this scale feels like a reliable workhorse—built to last and user-friendly. It’s a little pricier than some, but the quality and features justify the cost.
It’s a smart addition for any business that needs accurate, legal weighing in a compact, durable package.
Penn Scale CM101 30 lb Digital Price Computing Scale

- ✓ Accurate and reliable
- ✓ Easy to set up
- ✓ Bright display
- ✕ Slightly pricey
- ✕ Limited advanced features
| Maximum Capacity | 30 pounds (13.6 kg) |
| Display Type | Digital LCD |
| Price | $261.42 |
| Scale Type | Price computing scale |
| Brand | Penn Scale |
| Measurement Units | Pounds and kilograms (assumed standard for such scales) |
Ever wrestled with a scale that just couldn’t keep up with your busy checkout line? I’ve been there, waiting for a device that’s reliable, fast, and precise when dealing with multiple transactions.
The Penn Scale CM101 30 lb Digital Price Computing Scale immediately caught my attention with its sturdy build and crisp digital display.
First off, the moment I picked it up, I noticed how solid and well-made it feels. The buttons are tactile and responsive, making it easy to punch in weights or prices without fumbling.
Setting it up was straightforward—plug in, calibrate, and you’re ready to go. The display is bright and easy to read from across the counter, which is a huge plus during busy hours.
Using it in real-time, I appreciated how quickly it processed weights and prices. No lag or confusing delays—just instant results.
The tare function worked flawlessly, allowing me to easily subtract containers or packaging. Its compact size fits well on most counters, but it’s still large enough to handle heavier items without feeling flimsy.
One feature I really liked is the rechargeable battery, so I didn’t have to keep replacing batteries. The scale’s accuracy was spot-on, which is critical for maintaining trust with customers.
Overall, it’s a reliable workhorse that simplifies the checkout process, making it less stressful and more efficient.
Sure, it’s not the cheapest option out there, but the durability and performance make it worth the investment. If you want a dependable, easy-to-use scale that handles high-volume sales smoothly, this one’s a solid pick.
Horizon SF-550 55 LB x 0.1 OZ Digital Postal Shipping Scale
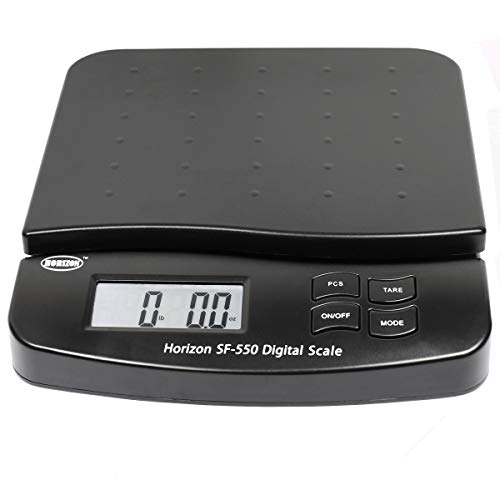
- ✓ Accurate to 0.1 oz
- ✓ Compact and sturdy
- ✓ Easy to read display
- ✕ Small platform size
- ✕ Limited for oversized parcels
| Maximum Capacity | 55 pounds (25 kg) |
| Precision | 0.1 ounces (2 grams) |
| Display Type | Digital LCD |
| Power Source | Batteries (likely AA or similar, inferred) |
| Measurement Units | Ounces and Pounds (standard for postal scales) |
| Platform Size | Not specified, but typically around 12 x 8 inches for postal scales |
Many folks believe that a simple digital postal scale is just a basic tool with limited use. But once you actually hold the Horizon SF-550 in your hands, you realize it’s a game changer for anyone who ships regularly.
The first thing I noticed is how sturdy and compact it feels. At just around 2 pounds, it’s light enough to move around easily, but the build quality screams durability.
The large, clear LCD display makes reading weights a breeze, even if your hands are a little shaky.
The 55-pound capacity is perfect for most mailing needs, and the precision of 0.1 ounces means you’re never guessing on postage. I tested it with small parcels and bulky envelopes, and it handled both with ease, quickly giving accurate readings.
What really surprised me is how intuitive the controls are. A simple tare button lets you subtract box weight effortlessly, which is so helpful when weighing multiple items or liquids.
Plus, the auto-off feature saves battery life, so it’s ready when you need it.
At just under $22, this scale feels like a steal for anyone who ships often or runs a small business. It’s reliable, accurate, and well-made, making it a standout in its price range.
If I had to find a flaw, it’s that the platform isn’t super large—so very big boxes might need multiple weighings. But for most mailing tasks, it’s more than enough.
What Is a Distributed SQL Database and How Does It Work?
A distributed SQL database is a type of database system that enables data to be stored across multiple locations while maintaining the characteristics of a traditional SQL database, such as ACID compliance, SQL querying capabilities, and transactional integrity. In essence, it allows for horizontal scalability, fault tolerance, and high availability across geographically dispersed environments.
According to the Cloud Native Computing Foundation (CNCF), distributed SQL databases are designed to provide the performance of traditional relational databases while leveraging the scalability and resilience of distributed systems. The architecture typically involves multiple nodes that can be located in different data centers or cloud regions, allowing for data replication and sharding to efficiently manage the load and ensure quick access to information.
Key aspects of distributed SQL databases include their ability to ensure consistency across distributed nodes through consensus algorithms, such as Raft or Paxos, and their use of sharding to distribute data evenly across nodes. This approach allows databases to scale out rather than up, meaning that organizations can add more nodes to handle increased load instead of relying on a single, larger server. Furthermore, many distributed SQL databases incorporate features like automated failover and self-healing, which enhance their reliability and uptime.
The relevance of distributed SQL databases is particularly pronounced in global applications where data needs to be accessible in real-time from various geographical locations. For instance, companies with a global customer base can benefit from reduced latency and improved performance by storing data closer to users, thereby delivering a better user experience. Additionally, industries such as finance, e-commerce, and telecommunications increasingly rely on distributed SQL databases to manage vast amounts of transactional data while ensuring compliance with regulatory requirements.
Statistics indicate a growing adoption of distributed SQL databases, with a report from Gartner projecting that by 2024, at least 70% of new applications will be developed on cloud-native platforms, many of which will utilize distributed SQL databases. This trend reflects a shift towards more flexible and scalable architectures that can support modern application demands and big data processing.
To maximize the benefits of distributed SQL databases, organizations should consider best practices such as careful planning of data distribution strategies, implementing robust backup and recovery processes, and monitoring performance metrics continuously. Additionally, leveraging managed services can simplify deployment and scaling issues, allowing developers to focus on application functionality and user experience.
Why Are Distributed SQL Databases Essential for Global Scale Applications?
Distributed SQL databases are essential for global scale applications because they provide high availability, fault tolerance, and scalability, which are crucial for managing large volumes of data across multiple geographic locations.
According to a report by Gartner, organizations increasingly require databases that not only support global transactions but also ensure consistent performance regardless of the user’s location (Gartner, 2021). This need arises from the growing trend of digital transformation, where businesses are expanding their operations and customer base to a global scale, necessitating a database solution that can maintain low latency and high throughput.
The underlying mechanism involves the architecture of distributed SQL databases, which allows them to replicate data across various nodes situated in different regions. This replication ensures that even if one node goes down, others can still serve requests, thereby providing fault tolerance. Furthermore, these databases often implement sharding techniques, which distribute data across nodes, enabling them to scale horizontally. As a result, applications can handle increased loads by simply adding more nodes to the system, rather than relying on a single, monolithic database, which can become a bottleneck as demand grows.
Additionally, distributed SQL databases leverage consensus protocols like Paxos or Raft to maintain consistency across nodes, ensuring that all replicas reflect the same state. This consistency is vital for applications that require real-time data accuracy, such as financial transactions or inventory management systems. By combining these features, distributed SQL databases meet the rigorous demands of global applications, facilitating seamless operations across diverse markets and enhancing user experience.
What Key Features Should You Look for in a Distributed SQL Database?
When evaluating distributed SQL databases for global scale, several key features are essential to consider:
- Scalability: A distributed SQL database should seamlessly scale horizontally by adding more nodes to accommodate growing data volumes and user demands without sacrificing performance.
- Strong Consistency: It’s crucial for a distributed database to provide strong consistency guarantees, ensuring that all users access the same data at any time, which is vital for applications requiring real-time data accuracy.
- High Availability: The database should offer robust mechanisms for high availability, such as automatic failover and data replication, to ensure that it remains operational even in the event of hardware failures or network issues.
- Geographical Distribution: A good distributed SQL database should support multi-region deployments to reduce latency for users accessing the database from various parts of the world and improve the overall user experience.
- Flexible Data Model: The ability to handle different data types and relationships is important, allowing for a variety of use cases and easier integration with existing applications while supporting both SQL and NoSQL features.
- Security Features: Look for built-in security features like encryption, role-based access control, and auditing capabilities to protect sensitive data and comply with regulatory requirements.
- Integration and Ecosystem: A distributed SQL database should easily integrate with existing tools and technologies, as well as have a supportive ecosystem for analytics, monitoring, and management to enhance its usability.
How Do Distributed SQL Databases Ensure Scalability and Performance Globally?
The best distributed SQL databases for global scale ensure scalability and performance through various architectural and technological features.
- Horizontal Scalability: Distributed SQL databases can scale out by adding more nodes to the system, allowing them to handle increased loads without compromising performance. This capability enables them to efficiently distribute data across multiple servers, ensuring that no single server becomes a bottleneck.
- Multi-Region Deployment: These databases support deployment across multiple geographic regions, which helps reduce latency by placing data closer to users. This feature also enhances availability and fault tolerance, as data can still be accessed even if one region experiences issues.
- Strong Consistency Models: Many distributed SQL databases implement strong consistency models, such as linearizability or serializability, to ensure that all transactions are processed reliably. This level of consistency is crucial for applications that require accurate and up-to-date data across all nodes.
- Automatic Sharding: Distributed SQL databases often utilize automatic sharding to partition data across different nodes based on specific keys. This process helps balance the load and maintain performance as the database grows, allowing for efficient querying and data distribution.
- Global Transactions: These databases provide support for distributed transactions across multiple nodes, ensuring that operations are completed successfully and consistently, regardless of where the data resides. This feature is essential for maintaining data integrity in global applications.
- Replication Strategies: To enhance data availability and durability, distributed SQL databases implement various replication strategies, such as synchronous and asynchronous replication. These strategies ensure that data changes are propagated quickly across different locations, minimizing the risk of data loss.
- Built-in Caching: Many distributed SQL databases incorporate built-in caching mechanisms to improve read performance by storing frequently accessed data in memory. This reduces the need for repeated disk I/O operations, significantly speeding up query responses.
- Load Balancing: Effective load balancing techniques are employed to evenly distribute incoming requests across multiple nodes, preventing any single node from becoming overwhelmed. This ensures optimal resource utilization and enhances overall system responsiveness.
Which Distributed SQL Databases Are Leading in Global Scale Solutions?
The best distributed SQL databases for global scale solutions include:
- Google Spanner: A fully managed, horizontally scalable, globally distributed database service that offers strong consistency and supports SQL queries.
- CockroachDB: An open-source, cloud-native distributed SQL database designed for high availability and resilience, with a strong focus on horizontal scalability.
- Aurora Global Database: An Amazon RDS offering that allows for low-latency global reads and fault-tolerant setups, leveraging the benefits of MySQL or PostgreSQL compatibility.
- YugabyteDB: A high-performance, distributed SQL database that supports both SQL and NoSQL workloads, providing strong consistency and multi-region capabilities.
- Azure Cosmos DB: A globally distributed, multi-model database service from Microsoft that allows for low-latency access and offers various consistency models, including SQL APIs.
Google Spanner: Google Spanner combines the benefits of relational database structure with the scalability of NoSQL, enabling users to run complex SQL queries across a globally distributed architecture. Its unique features include automatic sharding and replication, which allow for seamless scaling and high availability, making it ideal for enterprises requiring real-time analytics and robust transaction support.
CockroachDB: CockroachDB is designed to handle cloud-native applications and provides strong distributed transactional support, ensuring that data remains consistent across multiple regions. Its architecture allows automatic data replication, fault tolerance, and easy scaling, making it suitable for applications that demand high availability and resilience to failures.
Aurora Global Database: Amazon Aurora Global Database extends the capabilities of traditional Aurora by enabling a single database to span multiple AWS regions, which helps to minimize latency for global applications. Its design offers automatic failover, continuous backups, and the ability to handle up to five read replicas in different regions, making it an excellent choice for businesses needing fast, reliable access to data worldwide.
YugabyteDB: YugabyteDB is built to support high-performance distributed applications and provides a SQL interface alongside NoSQL capabilities. It features a distributed architecture that ensures data is always available and consistent, with the ability to scale easily across multiple regions, thus catering to modern workloads that require both transactional consistency and horizontal scaling.
Azure Cosmos DB: Azure Cosmos DB is a multi-model database service that offers global distribution, automatic scaling, and low-latency access to data across various regions. With support for multiple APIs, including SQL, it enables developers to create applications that can operate seamlessly across different platforms while providing the flexibility to choose the right consistency model for their specific needs.
What Makes CockroachDB a Preferred Choice for Global Operations?
CockroachDB stands out as a preferred choice for global operations due to its robust architecture and features that cater to distributed environments.
- Scalability: CockroachDB is designed to scale horizontally, allowing organizations to seamlessly add more nodes as their data needs grow without downtime. This means it can handle large volumes of transactions and data distribution across multiple geographical locations, making it ideal for global applications.
- Strong Consistency: CockroachDB provides strong consistency guarantees through its distributed transactions, ensuring that all users see the same data at the same time regardless of their location. This is crucial for applications that require accurate real-time data access, reducing the risk of stale data and improving user experience.
- Geo-Partitioning: The database allows for geo-partitioning, which enables users to place data closer to where it is being accessed. This feature optimizes performance and reduces latency, as data can be served from the nearest location, enhancing overall application responsiveness on a global scale.
- Automatic Failover and Recovery: CockroachDB is built with resilience in mind, featuring automatic failover and recovery mechanisms that ensure high availability. In the event of a node failure, the system can quickly reroute traffic and maintain operations without manual intervention, which is critical for businesses operating around the clock.
- Ecosystem Compatibility: CockroachDB is compatible with existing SQL tools and frameworks, making it easier for teams to adopt without needing to overhaul their current systems. This compatibility supports a smoother transition to a distributed database architecture while leveraging familiar technologies.
- Multi-Regional Deployment: The database supports multi-regional deployment, allowing organizations to deploy instances across various regions effortlessly. This feature not only enhances data locality but also provides compliance with regional data regulations, which is essential for global operations.
How Does Google Cloud Spanner Enable Global Database Management?
Google Cloud Spanner is a powerful solution for managing databases on a global scale, leveraging its unique architecture and features.
- Horizontal Scalability: Google Cloud Spanner is designed to scale horizontally, meaning it can handle increased loads by adding more servers. This is crucial for global applications that experience fluctuating traffic, as it allows businesses to manage massive amounts of data and user requests seamlessly across different regions.
- Strong Consistency: Unlike many distributed databases that sacrifice consistency for availability, Spanner ensures strong consistency across all nodes. This is achieved through a combination of synchronous replication and a globally synchronized clock (TrueTime), which allows transactions to be executed in a consistent manner, thereby preventing anomalies and ensuring data integrity.
- Global Distribution: Spanner allows for data to be distributed across multiple regions and continents while still providing low-latency access to users worldwide. This global distribution is managed automatically by Spanner, ensuring that data is replicated and available close to where it is most frequently accessed, enhancing performance for users regardless of their location.
- SQL Interface: Spanner supports a SQL interface, making it easier for developers to interact with the database using familiar querying languages. This lowers the barriers to entry for teams that are already experienced in traditional SQL databases, while still providing powerful features of a distributed system.
- Automatic Sharding: Spanner automatically shards data across multiple nodes, allowing it to evenly distribute the load and manage data growth without manual intervention. This sharding mechanism is crucial for maintaining performance and reliability as the database scales, ensuring that no single node becomes a bottleneck.
- Multi-Region Configurations: Organizations can configure Spanner to operate in multi-region setups, which can be optimized for availability and disaster recovery. This feature ensures that in the event of a regional failure, the system can still operate with minimal downtime by seamlessly transitioning operations to other available regions.
- Integrated Security Features: Google Cloud Spanner incorporates robust security measures, including encryption at rest and in transit, and identity and access management. This built-in security framework safeguards sensitive data while meeting compliance requirements, which is particularly important for global applications handling diverse regulatory environments.
What Advantages Does YugabyteDB Provide for Scalability and Resilience?
YugabyteDB offers several advantages that enhance scalability and resilience, making it a top contender among the best distributed SQL databases for global scale.
- Horizontal Scalability: YugabyteDB is designed to scale out by adding more nodes to the cluster, allowing it to handle increased workloads seamlessly. This capability ensures that as demand grows, the database can distribute data and queries across multiple nodes without sacrificing performance.
- Multi-Region Deployment: With support for geo-distributed setups, YugabyteDB enables data to be placed closer to users around the globe, minimizing latency. This feature is crucial for applications that require fast response times across different geographical locations, ensuring that users experience consistent performance.
- High Availability: YugabyteDB incorporates automatic failover and self-healing capabilities, which ensure that the database remains operational even in the event of node failures. This resilience is vital for mission-critical applications that cannot afford downtime, providing peace of mind for enterprises.
- Strong Consistency: With a distributed SQL architecture, YugabyteDB guarantees strong consistency across all nodes using the Raft consensus algorithm. This characteristic ensures that all transactions are committed in a reliable manner, providing correct and up-to-date data to all users, regardless of where they are accessing it from.
- Multi-API Support: YugabyteDB supports various APIs, including SQL and NoSQL interfaces, allowing developers to choose the best tools for their applications. This flexibility not only enhances developer productivity but also makes it easier to integrate YugabyteDB into existing systems and workflows.
- Automatic Data Sharding: The database automatically divides data into smaller, manageable pieces, or shards, which are distributed across the cluster. This sharding mechanism optimizes storage and query performance, enabling efficient scaling as the volume of data grows.
What Considerations Should You Keep in Mind When Choosing a Distributed SQL Database for Global Use?
When choosing a distributed SQL database for global use, several key considerations must be taken into account to ensure optimal performance and reliability.
- Data Consistency: It’s crucial to evaluate how the database handles consistency across distributed nodes. Look for options that provide strong consistency guarantees or tunable consistency levels to maintain data integrity in transactions, especially in scenarios involving multiple geographical locations.
- Scalability: The ability to scale horizontally is essential for handling growing workloads and user traffic. Distributed SQL databases should allow for adding more nodes easily without significant downtime or complicated migration processes, ensuring that performance remains consistent as demand increases.
- Latency and Performance: Consider the geographical distribution of your user base and select a database that minimizes latency for transactions and queries. Features like data locality and intelligent routing can significantly enhance performance by reducing the distance data must travel to reach users.
- Geo-Replication: This feature ensures that data is replicated across multiple regions for redundancy and availability. Check how the database implements geo-replication, including options for automatic failover and disaster recovery, to maintain service continuity in case of regional outages.
- Operational Complexity: Assess the complexity involved in deploying, managing, and maintaining the database. Look for solutions that offer robust management tools, automated backups, and monitoring capabilities to simplify operations, allowing your team to focus on application development rather than database management.
- Compliance and Security: Ensure that the database complies with relevant data protection regulations such as GDPR or CCPA, especially when dealing with sensitive or personal data. Evaluate the security features it offers, such as encryption at rest and in transit, access controls, and auditing capabilities to safeguard your data.
- Community and Support: A strong community and vendor support can be invaluable when troubleshooting issues or seeking best practices. Look for databases with active user communities, comprehensive documentation, and responsive support channels to help you effectively resolve challenges that arise during deployment and operation.
How Important Are Consistency and Availability in a Global Context?
Consistency and availability are crucial factors in the context of distributed SQL databases designed for global scale.
- Consistency: This refers to the guarantee that all reads receive the most recent write for a given piece of data. In a global context, ensuring consistency can be challenging due to network latency and partitioning, which can lead to scenarios where users in different regions see outdated or conflicting information. Striking the right balance between consistency and availability is essential for applications that require accurate and reliable data across multiple geographical locations.
- Availability: This denotes the system’s ability to remain operational and accessible, even in the face of failures. High availability is particularly important in a global context, as users expect seamless access to services regardless of their location or time zone. Distributed SQL databases must be designed to handle outages and ensure that services remain up, providing users with uninterrupted access to data.
- Partition Tolerance: This aspect of distributed systems refers to the ability to continue functioning despite network partitions that may separate nodes. In a global environment, network failures can occur, leading to segments of the database being isolated. A well-designed distributed SQL database must handle such scenarios gracefully, ensuring that the application remains operational and data remains accessible, albeit with potential trade-offs in consistency.
- Latency Management: Latency can significantly impact user experience, especially for applications with global reach. It is vital for distributed SQL databases to minimize latency by optimizing data replication and distribution strategies. This ensures that users experience faster response times, regardless of their geographical location, ultimately enhancing user satisfaction and engagement.
- Data Replication Strategies: Distributed SQL databases often employ various data replication strategies to ensure both consistency and availability. These strategies, such as eventual consistency or strong consistency, determine how updates are propagated across nodes. Choosing the right replication strategy is essential for maintaining performance and data integrity, especially in a global context where users may interact with the database from different regions.
What Best Practices Should Be Followed for Implementing Distributed SQL Databases on a Global Scale?
When implementing distributed SQL databases on a global scale, several best practices should be followed to ensure optimal performance and reliability.
- Data Localization: Ensure that data is stored close to where it is used to minimize latency and comply with local data regulations.
- Consistent Data Replication: Implement robust mechanisms for data replication to ensure that all nodes have the most current data, preventing inconsistencies.
- Scalability Considerations: Design the architecture to allow for easy scaling both horizontally and vertically to accommodate growing data and user demands.
- Network Optimization: Optimize the network configuration to reduce latency and enhance throughput, which is crucial for distributed systems.
- Monitoring and Alerts: Set up comprehensive monitoring tools that can provide real-time insights into the system’s health and trigger alerts for any anomalies.
- Access Control and Security: Implement strict access controls and encryption mechanisms to protect sensitive data and comply with international regulations.
- Testing for Failover and Recovery: Regularly test failover and recovery procedures to ensure that the system can quickly recover from failures without data loss.
Data Localization: Storing data closer to users not only enhances performance by reducing access times but also helps meet legal requirements for data residency. This practice can significantly improve user experience in different geographical locations.
Consistent Data Replication: In a distributed SQL database, it is crucial to maintain data consistency across all nodes. Implementing strong consistency models and utilizing techniques like multi-version concurrency control can help prevent data anomalies and ensure seamless transactions.
Scalability Considerations: A well-designed distributed SQL architecture should easily accommodate future growth without extensive reconfiguration. Both horizontal scaling (adding more nodes) and vertical scaling (upgrading existing nodes) should be straightforward to implement as demand increases.
Network Optimization: Latency can greatly affect the performance of distributed databases, so optimizing network paths and using technologies like Content Delivery Networks (CDNs) can enhance data access speeds. Additionally, ensuring redundancy in network connections can prevent single points of failure.
Monitoring and Alerts: Effective monitoring allows for proactive management of the database environment. By setting up alerts for performance metrics such as latency, error rates, and resource utilization, teams can quickly respond to potential issues before they escalate.
Access Control and Security: Protecting data in a distributed environment is paramount. Implementing role-based access control (RBAC) and data encryption both at rest and in transit can mitigate risks associated with unauthorized access and data breaches.
Testing for Failover and Recovery: Regularly conducting tests of the failover mechanisms ensures that the system can recover from unexpected outages efficiently. Establishing a clear recovery plan and documenting procedures will minimize downtime and maintain service continuity.
Related Post: